jingzhang
Many users have pointed out that while DeepSeek-V3.2’s long-thinking enhanced version, Speciale, has indeed put pressure on top closed-source models as an open-source solution, it also comes with a clear issue:When tackling complex tasks, it consumes an unusually high number of tokens — sometimes producing answers that are long but incorrect.For example, when solving the same problem:
- Gemini used just 20,000 tokens
- Speciale used up to 77,000 tokens
So, what’s going on?
Unresolved “Length Bias”Some researchers have noted that this is actually an old “bug” that has persisted in the DeepSeek series since DeepSeek-R1-Zero.In short, the issue lies in the GRPO algorithm (Group Relative Policy Optimization).Researchers from institutions such as Sea AI Lab and the National University of Singapore have pointed out that GRPO contains two hidden biases:
1. Length Bias: The Longer the Wrong Answer, the Lighter the Penalty
When calculating rewards, GRPO takes answer length into account — and as a result, shorter wrong answers are penalized more harshly than longer ones.This leads to a counterintuitive behavior:The model tends to generate longer, incorrect answers that may look like it’s “thinking deeply” or “reasoning step-by-step,” but is actually padding its response to avoid penalties.
2. Difficulty Bias: Overemphasis on Extremely Easy or Hard Questions
GRPO adjusts the weight of questions based on the score standard deviation within a batch.
- If everyone gets a question right (low standard deviation), or everyone gets it wrong (also low standard deviation), that question is treated as a “focus point” and gets repeated training.
- Meanwhile, medium-difficulty questions — where some get it right and some don’t (high standard deviation) — are often ignored.
But in reality, medium-difficulty questions are the most valuable for improving a model’s capabilities.
Progress Made, But the Bias Remains
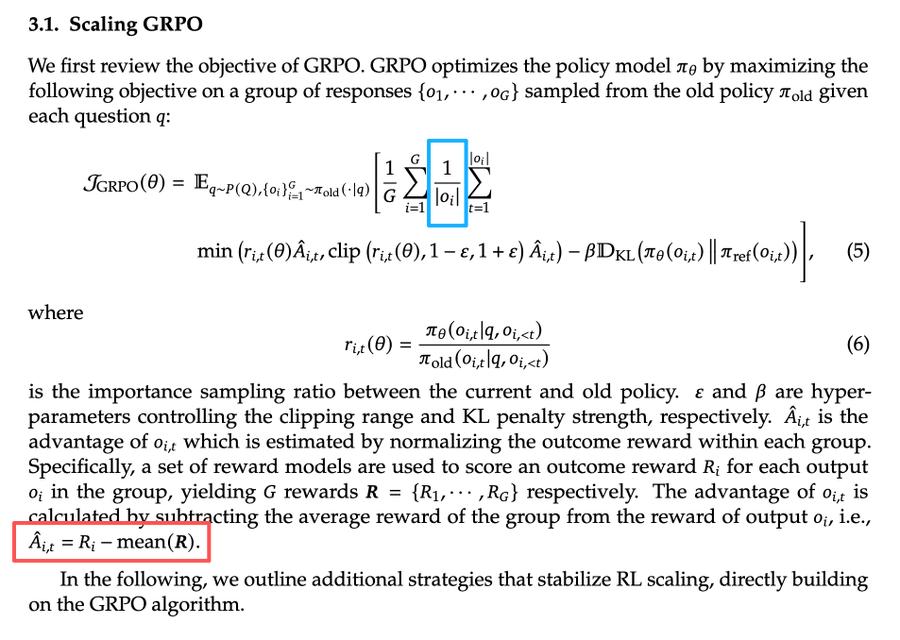
Zichen Liu, the lead author of the study, pointed out that DeepSeek-V3.2 has already fixed the “difficulty bias” by introducing a new advantage value calculation method (as highlighted in the red box in the diagram below).However, the biased length normalization term still remains (blue box in the diagram).That means: the length bias is still there.
Official Acknowledgement from DeepSeek
Interestingly, this issue has also been mentioned in DeepSeek’s own technical report.The researchers admitted that token efficiency remains a challenge for DeepSeek-V3.2:In general, the two newly released models need to generate longer response trajectories to match the output quality of Gemini-3.0-Pro.Speciale, in particular, was designed with relaxed RL length limits, allowing the model to produce extremely long reasoning chains. This approach enables deep self-correction and exploration — but at the cost of burning a lot of tokens.In essence, DeepSeek is taking a path of “continuously extending reinforcement learning under ultra-long contexts.”That said, considering the cost per million tokens, DeepSeek-V3.2 is priced at just 1/24th of GPT-5, which may be seen as a reasonable trade-off.
Also Worth Noting: 128K Context Limit
Additionally, some users have pointed out that DeepSeek’s 128K context window hasn’t been updated in a long time — which may also be related to limited GPU resources.
Define the settlement base before automating payouts
Revenue-sharing logic needs an explicit definition of eligible revenue. Gross purchase value, payment fees, refunds, taxes, platform share and creator share should be represented clearly before any on-chain or automated settlement runs.
A smart contract can execute a formula perfectly and still produce the wrong business outcome if the formula itself is ambiguous.
Design for corrections rather than assuming finality
Refunds, chargebacks and attribution changes often arrive after an initial payout calculation. Append-only correction records or reserve mechanisms can preserve auditability without pretending the first calculation can never change.
The system should show both the original event and the later adjustment so creators can reconcile balances over time.
Connect wallet actions to human-readable intent
Before a user or agent signs a transaction, the product should display what asset moves, how much, to whom and under which limits. Machine-readable constraints are valuable, but the final authorization still needs to be understandable to the person responsible for the wallet.
Clear intent reduces the risk of technically valid transactions that do something the user did not expect.

 admin